class: center middle main-title section-title-4 # Displaying data .class-info[ **Topic 2 · Thursday, January 7** .light[EDUC 15: Statistics for Education Research<br> UCI School of Education ] ] --- class: title title-8 # Where are we? .pull-left-3[ .box-1.medium[Description] .box-inv-1.small[Summarize data] .box-inv-1.small[Visualize data] .center[**We are here**] .anteater[] ] .pull-middle-3[ .box-6.medium[Prediction] ] .pull-right-3[ .box-3.medium[Explanation] ] .source[Peter the Anteater at a UC Irvine basketball game.] ??? Statistics has three purposes, and we start with the first. Today is about seeing data. Next week we summarize it in a few numbers. --- name: outline class: title title-8 # Plan for today .box-1.medium.sp-after-half[The Mindspark study] .box-6.medium.sp-after-half[Frequency tables] .box-3.medium.sp-after-half[Plots and shapes] ??? Three blocks of about 20 minutes. Each ends with students doing something: predict, try, predict. --- layout: false class: center middle section-title section-title-1 animated fadeIn # The Mindspark study --- layout: true class: title title-1 --- # Recap: The Mindspark study .box-1.small.sp-after-half[Does the Mindspark program improve children's learning?] .pull-left-3[ .box-inv-1.small[Where] After-school centers in Delhi, India .picture-small[] ] .pull-middle-3[ .box-inv-1.small[Who] 619 children, mostly in grades 6 to 9 ] .pull-right-3[ .box-inv-1.small[What] Software that adapts to each child, plus small-group help from a teaching assistant ] .source[Muralidharan, Singh, and Ganimian (2019), *American Economic Review* 109(4). Photo: a Mindspark center.] ??? A quick recap from Tuesday. We'll use this study all quarter, so every new method gets tried on these same children. Each session was about 45 minutes on the software and 45 minutes with a teaching assistant. --- # A lottery split the 619 students in two .flow[ .flow-box[ **Population** Students like these ] .flow-step[ Sampling → ] .flow-box[ **Sample** 619 children ] .flow-step[ Random assignment → ] .flow-pair[ .flow-box[ **Treatment**, n = 314 Free access now ] .flow-box[ **Control**, n = 305 Promised the program later ] ] ] .box-1.small[Luck alone decided who got it. That makes this an experiment] .source[Muralidharan, Singh, and Ganimian (2019).] ??? Be honest about the first arrow. These children applied for the lottery, so the sample isn't a random draw from any population. Who the population is remains a real question, as we said Tuesday. The second arrow really is random. We come back to this picture of population, sample and groups all quarter. --- # We have scores from before and after .pull-left[ .box-inv-1.medium[Baseline] .center[Before the program Math and Hindi tests **619 students**] ] .pull-right[ .box-inv-1.medium[Endline] .center[About 4.5 months later Math and Hindi tests **539 students**] ] .box-1.small[Today we start with one column: math scores at baseline] .source[Data: Muralidharan, Singh, and Ganimian (2019).] ??? 80 students didn't take the endline tests. We'll say more about that in Topic 14. --- # Tidy data .picture[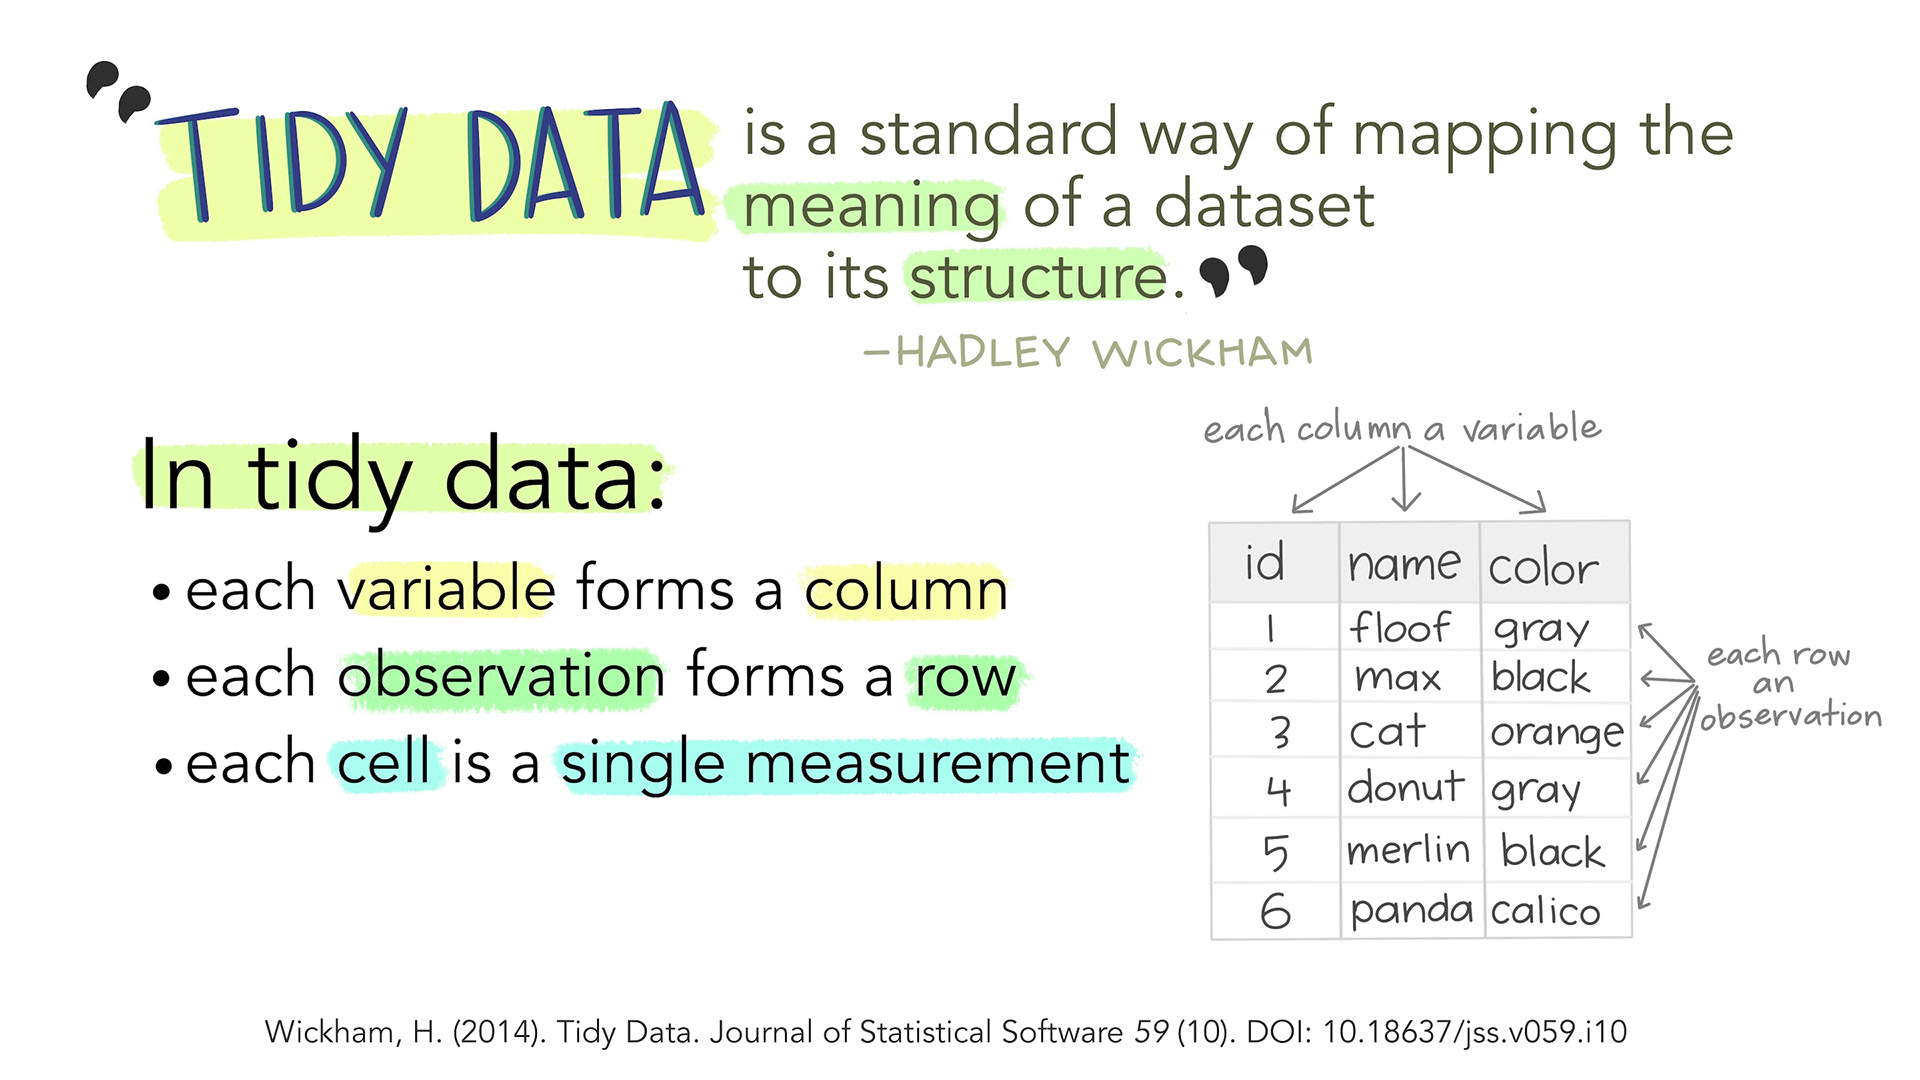] .source[Illustration: Lowndes and Horst (2020), [Openscapes blog](https://openscapes.org/blog/2020-10-12-tidy-data/), CC BY 4.0. Wickham (2014), *Journal of Statistical Software* 59(10).] --- # Tidy data: One student, one row <table class="deck-table tight"> <thead> <tr> <th style="text-align:left;"> Student </th> <th style="text-align:left;"> Center </th> <th style="text-align:center;"> Grade </th> <th style="text-align:center;"> Female </th> <th style="text-align:center;"> Treatment </th> <th style="text-align:center;"> Hindi </th> <th style="text-align:center;"> Math </th> </tr> </thead> <tbody> <tr> <td style="text-align:left;"> CH002 </td> <td style="text-align:left;"> Chhatarpur </td> <td style="text-align:center;"> 7 </td> <td style="text-align:center;"> 1 </td> <td style="text-align:center;"> 0 </td> <td style="text-align:center;"> 17 </td> <td style="text-align:center;"> 12 </td> </tr> <tr> <td style="text-align:left;"> CH003 </td> <td style="text-align:left;"> Chhatarpur </td> <td style="text-align:center;"> 8 </td> <td style="text-align:center;"> 1 </td> <td style="text-align:center;"> 0 </td> <td style="text-align:center;"> 13 </td> <td style="text-align:center;"> 12 </td> </tr> <tr> <td style="text-align:left;"> CH004 </td> <td style="text-align:left;"> Chhatarpur </td> <td style="text-align:center;"> 5 </td> <td style="text-align:center;"> 1 </td> <td style="text-align:center;"> 0 </td> <td style="text-align:center;"> 10 </td> <td style="text-align:center;"> 13 </td> </tr> <tr> <td style="text-align:left;"> CH005 </td> <td style="text-align:left;"> Chhatarpur </td> <td style="text-align:center;"> 7 </td> <td style="text-align:center;"> 1 </td> <td style="text-align:center;"> 0 </td> <td style="text-align:center;"> 12 </td> <td style="text-align:center;"> 8 </td> </tr> <tr> <td style="text-align:left;"> CH007 </td> <td style="text-align:left;"> Chhatarpur </td> <td style="text-align:center;"> 6 </td> <td style="text-align:center;"> 1 </td> <td style="text-align:center;"> 1 </td> <td style="text-align:center;"> 13 </td> <td style="text-align:center;"> 13 </td> </tr> <tr> <td style="text-align:left;"> CH008 </td> <td style="text-align:left;"> Chhatarpur </td> <td style="text-align:center;"> 6 </td> <td style="text-align:center;"> 1 </td> <td style="text-align:center;"> 0 </td> <td style="text-align:center;"> 11 </td> <td style="text-align:center;"> 12 </td> </tr> </tbody> </table> .box-1.small.sp-after-half[Each variable is a column. Each observation is a row. Each cell is one measurement] .box-inv-1.small[That's the first 6 of 619 rows. Lab 1 opens the whole file] .source[Data: Muralidharan, Singh, and Ganimian (2019). Tidy data: Wickham (2014), *Journal of Statistical Software* 59(10).] ??? Female and Treatment are coded 1 for yes and 0 for no. Scale check from Tuesday: which of these columns are nominal? Which are numbers we could average? --- # Tidy, but where is the pattern? <img src="02-displaying-data_files/figure-html/wall-1.png" alt="A dense wall of all 619 baseline math scores, printed as numbers in rows, in the order they appear in the data file. No pattern is visible." width="90%" style="display: block; margin: auto;" /> .source[All 619 baseline math scores. Data: Muralidharan, Singh, and Ganimian (2019).] ??? Give them a moment with this. It's all here, and nobody can see a thing. That's the problem today solves. --- layout: false class: title title-8 poll-slide # Predict it: The most common score .poll-respond[Respond at **PollEv.com/adb**] .box-inv-8.small[ You just saw all 619 scores. The test has 35 points. Which score do you think came up most often? ] .options[ .option[ **A** 6 ] .option[ **B** 12 ] .option[ **C** 18 ] .option[ **D** 24 ] ] ??? About 6 minutes. Vote, turn to a neighbor, vote again, then show the answer. Andy: create this poll in Poll Everywhere, then add the `.poll-bar` button from EDUC 265's 06-01 with its presenter id. --- class: title title-8 poll-answer # Predict it: Answer .options[ .option.wrong[ **A** 6 ] .option.correct[ **B** 12 ] .option.wrong[ **C** 18 ] .option.wrong[ **D** 24 ] ] .box-inv-8.small.sp-after-half[ 76 students scored 12. That score is about a third of the 35 points ] .box-8.small[ Nobody can see that in a wall of numbers. A simple table finds it in seconds ] .source[Data: Muralidharan, Singh, and Ganimian (2019).] --- layout: false class: center middle section-title section-title-6 animated fadeIn # Frequency tables --- layout: true class: title title-6 --- # A frequency table counts each score .pull-left[ .box-inv-6.small[Left column: each score X] .box-inv-6.small[Right column: how many students, called the frequency f] .box-6.small[Show every category, even a zero] ] .pull-right[ <table class="deck-table tight"> <thead> <tr> <th style="text-align:center;"> Score X </th> <th style="text-align:center;"> f </th> </tr> </thead> <tbody> <tr> <td style="text-align:center;"> 20 </td> <td style="text-align:center;"> 4 </td> </tr> <tr> <td style="text-align:center;"> 21 </td> <td style="text-align:center;"> 5 </td> </tr> <tr> <td style="text-align:center;"> 22 </td> <td style="text-align:center;"> 0 </td> </tr> <tr> <td style="text-align:center;"> 23 </td> <td style="text-align:center;"> 1 </td> </tr> <tr> <td style="text-align:center;"> 24 </td> <td style="text-align:center;"> 1 </td> </tr> <tr> <td style="text-align:center;"> 25 </td> <td style="text-align:center;"> 0 </td> </tr> <tr> <td style="text-align:center;"> 26 </td> <td style="text-align:center;"> 1 </td> </tr> </tbody> </table> .center.small[Nobody scored 22 or 25] ] .source[Data: Muralidharan, Singh, and Ganimian (2019).] ??? A gap in the table would hide something real: nobody scored 22. The next slide has the full table. These are whole-number scores. The test could give anything from 0 to 35, and the highest anyone scored was 26. The book lists the highest score at the top. Either order is fine. --- # The full table has a peak at 12 <table class="deck-table tight tighter"> <thead> <tr> <th style="text-align:center;"> Score X </th> <th style="text-align:center;"> f </th> <th style="text-align:center;"> Score X </th> <th style="text-align:center;"> f </th> <th style="text-align:center;"> Score X </th> <th style="text-align:center;"> f </th> </tr> </thead> <tbody> <tr> <td style="text-align:center;"> 0 </td> <td style="text-align:center;"> 2 </td> <td style="text-align:center;"> 9 </td> <td style="text-align:center;"> 55 </td> <td style="text-align:center;"> 18 </td> <td style="text-align:center;"> 13 </td> </tr> <tr> <td style="text-align:center;"> 1 </td> <td style="text-align:center;"> 1 </td> <td style="text-align:center;"> 10 </td> <td style="text-align:center;"> 66 </td> <td style="text-align:center;"> 19 </td> <td style="text-align:center;"> 9 </td> </tr> <tr> <td style="text-align:center;"> 2 </td> <td style="text-align:center;"> 4 </td> <td style="text-align:center;"> 11 </td> <td style="text-align:center;"> 60 </td> <td style="text-align:center;"> 20 </td> <td style="text-align:center;"> 4 </td> </tr> <tr> <td style="text-align:center;"> 3 </td> <td style="text-align:center;"> 11 </td> <td style="text-align:center;"> <strong class="peak">12</strong> </td> <td style="text-align:center;"> <strong class="peak">76</strong> </td> <td style="text-align:center;"> 21 </td> <td style="text-align:center;"> 5 </td> </tr> <tr> <td style="text-align:center;"> 4 </td> <td style="text-align:center;"> 10 </td> <td style="text-align:center;"> 13 </td> <td style="text-align:center;"> 48 </td> <td style="text-align:center;"> 22 </td> <td style="text-align:center;"> 0 </td> </tr> <tr> <td style="text-align:center;"> 5 </td> <td style="text-align:center;"> 23 </td> <td style="text-align:center;"> 14 </td> <td style="text-align:center;"> 61 </td> <td style="text-align:center;"> 23 </td> <td style="text-align:center;"> 1 </td> </tr> <tr> <td style="text-align:center;"> 6 </td> <td style="text-align:center;"> 20 </td> <td style="text-align:center;"> 15 </td> <td style="text-align:center;"> 33 </td> <td style="text-align:center;"> 24 </td> <td style="text-align:center;"> 1 </td> </tr> <tr> <td style="text-align:center;"> 7 </td> <td style="text-align:center;"> 34 </td> <td style="text-align:center;"> 16 </td> <td style="text-align:center;"> 24 </td> <td style="text-align:center;"> 25 </td> <td style="text-align:center;"> 0 </td> </tr> <tr> <td style="text-align:center;"> 8 </td> <td style="text-align:center;"> 43 </td> <td style="text-align:center;"> 17 </td> <td style="text-align:center;"> 14 </td> <td style="text-align:center;"> 26 </td> <td style="text-align:center;"> 1 </td> </tr> </tbody> </table> .box-inv-6.small[The f column adds up to n = 619, so every student is counted once] .source[Data: Muralidharan, Singh, and Ganimian (2019). In the book, this total is written N.] --- # Grouping trades detail for clarity .pull-left[ .box-inv-6.small[Ten or fewer intervals is typical] .box-inv-6.small[Use a simple width: 2, 5, 10 or 20] .box-inv-6.small[Start at a multiple of the width] .box-inv-6.small[Keep all intervals the same width] ] .pull-right[ <table class="deck-table tight"> <thead> <tr> <th style="text-align:center;"> Interval </th> <th style="text-align:center;"> f </th> </tr> </thead> <tbody> <tr> <td style="text-align:center;"> 0–4 </td> <td style="text-align:center;"> 28 </td> </tr> <tr> <td style="text-align:center;"> 5–9 </td> <td style="text-align:center;"> 175 </td> </tr> <tr> <td style="text-align:center;"> 10–14 </td> <td style="text-align:center;"> 311 </td> </tr> <tr> <td style="text-align:center;"> 15–19 </td> <td style="text-align:center;"> 93 </td> </tr> <tr> <td style="text-align:center;"> 20–24 </td> <td style="text-align:center;"> 11 </td> </tr> <tr> <td style="text-align:center;"> 25–29 </td> <td style="text-align:center;"> 1 </td> </tr> </tbody> </table> ] .box-6.small[Inside 10–14, we no longer know any one student's exact score] .source[Data: Muralidharan, Singh, and Ganimian (2019).] ??? These are guidelines, so use good judgment. With a width of 5 we get six intervals, down from 27 rows. --- layout: false class: title title-8 # Try it: Group 20 real scores .box-inv-8.medium.sp-after-half[11, 10, 12, 9, 8, 8, 6, 8, 11, 12, 8, 16, 4, 9, 10, 10, 12, 13, 14, 10] .box-8.small.sp-after-half[Make a grouped table with intervals of 5, starting at 0. Then check your total] .box-inv-8.small[Work alone for two minutes. Compare with a neighbor. Then we vote: how many fall in 5–9?] .source[Data: Muralidharan, Singh, and Ganimian (2019). A random draw of 20 students.] ??? About 6 minutes. Students who finish early can sketch a histogram of their table, as a preview. Vote by hands. --- class: title title-8 # Try it: Answer <table class="deck-table tight"> <thead> <tr> <th style="text-align:center;"> Interval </th> <th style="text-align:center;"> f </th> </tr> </thead> <tbody> <tr> <td style="text-align:center;"> 0–4 </td> <td style="text-align:center;"> 1 </td> </tr> <tr> <td style="text-align:center;"> 5–9 </td> <td style="text-align:center;"> 7 </td> </tr> <tr> <td style="text-align:center;"> 10–14 </td> <td style="text-align:center;"> 11 </td> </tr> <tr> <td style="text-align:center;"> 15–19 </td> <td style="text-align:center;"> 1 </td> </tr> </tbody> </table> .box-inv-8.small.sp-after-half[The total is 20, one count per student. Nobody got lost] .box-8.small[Even these 20 peak at 10–14, the same interval as all 619] .source[Data: Muralidharan, Singh, and Ganimian (2019).] --- layout: false class: center middle section-title section-title-3 animated fadeIn # Plots and shapes --- layout: true class: title title-3 --- # A histogram draws the grouped table <img src="02-displaying-data_files/figure-html/histogram-1.png" alt="Histogram of baseline math scores in intervals of 5, with touching bars labeled with their counts: 0–4 has 28, 5–9 has 175, 10–14 has 311, 15–19 has 93, 20–24 has 11, 25–29 has 1. The tallest bar is 10–14." width="84%" style="display: block; margin: auto;" /> .box-inv-3.small[Each bar is one row of the table. The bars touch: the scale has no gaps] .source[Data: Muralidharan, Singh, and Ganimian (2019).] --- # A polygon swaps bars for dots and lines <img src="02-displaying-data_files/figure-html/polygon-grouped-1.png" alt="The same histogram in pale blue, with a dark line on top. Each dot sits at the middle of an interval at the height of its bar, and the line drops to zero at both ends. The line rises to a peak at the interval from 10 to 14 and then falls." width="84%" style="display: block; margin: auto;" /> .box-inv-3.small[Each dot sits at the middle of its interval. A line is easier to overlay than bars] .source[Data: Muralidharan, Singh, and Ganimian (2019).] ??? The line drops to zero one interval past each end, so the shape closes on the axis. --- # Every score: more detail, more bumps <img src="02-displaying-data_files/figure-html/polygon-full-1.png" alt="A polygon with one dot for every score from 0 to 26. It rises to a jagged peak of 76 students at a score of 12, with a sharp dip right after it, and then falls to almost nothing above 20." width="84%" style="display: block; margin: auto;" /> .box-inv-3.small[With no grouping we keep every count, and the picture gets jagged] .source[Data: Muralidharan, Singh, and Ganimian (2019).] --- # Percentages put groups on one scale <img src="02-displaying-data_files/figure-html/percentages-1.png" alt="Two polygons of baseline math scores for 470 girls and 149 boys. In the left panel, which shows counts, the line for girls towers over the line for boys. In the right panel, which shows the percent of each group, the two lines have nearly the same height and shape." width="90%" style="display: block; margin: auto;" /> .box-inv-3.small[% = 100 × f / n. On the left, size hides the shape. On the right, we can compare] .source[Data: Muralidharan, Singh, and Ganimian (2019).] ??? The shapes are the point. Girls and boys look much alike once we use percentages. There are simply about 3 times as many girls in this sample. --- # A density plot smooths out the bumps <img src="02-displaying-data_files/figure-html/density-1.png" alt="The percentage of students at each math score, shown as pale bars, with a smooth dark curve running through them. The curve has one peak near 12 and falls away evenly on both sides." width="80%" style="display: block; margin: auto;" /> .box-inv-3.small[It adds up a small bump at each score. You'll read these, not compute them] .source[Data: Muralidharan, Singh, and Ganimian (2019).] ??? The name is fancy, the idea isn't. Smooth curves are how we'll draw distributions for the rest of the quarter, starting with the normal curve. --- # Categories get bars with gaps <img src="02-displaying-data_files/figure-html/bar-graph-1.png" alt="Bar graph of students at the three Mindspark centers, with gaps between the bars: Chhatarpur has 161, Govindpuri has 82, Tekhand has 376." width="80%" style="display: block; margin: auto;" /> .box-inv-3.small[Scores have an order and even steps, so a histogram's bars touch. Centers are just names, so these bars stand apart] .source[Data: Muralidharan, Singh, and Ganimian (2019).] ??? This is Tuesday's scales of measurement at work. Nominal and ordinal variables get a bar graph. Interval and ratio variables get a histogram or polygon. --- # Symmetric, unimodal and normal differ <img src="02-displaying-data_files/figure-html/shapes-1.png" alt="Three curves side by side. The first has two equal peaks and mirrors around its center, so it's symmetric but not unimodal. The second has one peak on the left and a long tail to the right, so it's unimodal but not symmetric. The third is a bell curve: symmetric, unimodal and normal." width="92%" style="display: block; margin: auto;" /> .pull-left-3[ .box-inv-3.small[Symmetric: each side mirrors the other] ] .pull-middle-3[ .box-inv-3.small[Unimodal: one high point] ] .pull-right-3[ .box-inv-3.small[Normal: a bell, common in nature] ] ??? A normal distribution is symmetric and unimodal, with the most scores in the middle. Not every symmetric, unimodal shape is normal, but that's a detail for later. Our math scores are unimodal and close to symmetric. Many measurements in nature look like this, which is why the bell curve keeps coming back. --- # Not everything is normal .picture[] .source[Artwork by @allison_horst, CC BY 4.0.] --- # Skewed distributions have one long tail <img src="02-displaying-data_files/figure-html/skew-1.png" alt="Two curves. On the left, a peak near the high end with a long tail stretching to the left, labeled skewed left. On the right, a peak near the low end with a long tail stretching to the right, labeled skewed right." width="90%" style="display: block; margin: auto;" /> .pull-left[ .box-inv-3.small[A very easy test: scores pile up high, and a few trail off to the left] ] .pull-right[ .box-inv-3.small[A very hard test: scores pile up low, and a few trail off to the right] ] .book-tag[In the book: skewed left is negatively skewed, and skewed right is positively skewed] ??? Skew is named after the tail, not the peak. That's the common mistake. Tuesday we'll see what a long tail does to the mean. --- # Everybody loves a doggo mnemonic .picture[] .source[Jawlik, *Statistics from A to Z: Confusing Concepts Clarified* (Wiley, 2016), [statisticsfromatoz.com](https://www.statisticsfromatoz.com/blog/statistics-tip-the-skew-is-in-the-direction-of-the-long-tail).] ??? The skew goes the way the dog's tail points. --- layout: false class: title title-8 # Predict it: The endline scores .box-inv-8.small.sp-after-half[The same study, about 4.5 months later. Picture the baseline curve you just saw. What does the endline curve look like?] .options[ .option[ **A** In about the same place ] .option[ **B** Moved right, still one peak ] .option[ **C** Moved right, now two peaks ] .option[ **D** Moved left ] ] .box-8.small[Tell a neighbor why. Half these students had Mindspark, and half didn't] ??? About 6 minutes. Hands are fine here. Ask a few students to defend their answer before the next slide, especially anyone who picked C. If half got a program and half didn't, why wouldn't we see two peaks? --- class: title title-8 # Predict it: The whole pile moved right <img src="02-displaying-data_files/figure-html/endline-1.png" alt="Two smooth curves of math scores, on a percent scale. The baseline curve, for 619 students, peaks near 12. The endline curve, for 539 students, sits about 6 points to the right. It's wider and lower, with one broad peak." width="82%" style="display: block; margin: auto;" /> .box-inv-8.small[So, B: one wide peak. Half the students scored at least 11 at baseline, and half at least 17 at endline] .source[Data: Muralidharan, Singh, and Ganimian (2019).] ??? Percentages again, because the two rounds have different numbers of students. Why not two peaks, with one group ahead? At endline the treatment group's mean is about 2.7 points higher, but scores spread much wider than that, so the two piles overlap into one. Why did the pile move? Everyone had 4.5 more months of school, and half also had Mindspark. A plot of everyone can't separate those two. That's what the rest of the course is for: this is description, and explanation comes later. The endline tests aren't identical to the baseline test. They were out of 34 or 35, depending on the grade band. So treat this as a rough picture. --- layout: false class: title title-8 # What you can do now .box-inv-8.small[Say what the Mindspark study did, and why it used a lottery] .box-inv-8.small[Build a frequency table, ungrouped or grouped] .box-inv-8.small[Read a histogram, a polygon, a density plot and a bar graph] .box-inv-8.small[Describe a shape: symmetric, unimodal, normal or skewed] --- class: title title-8 # Next steps .pull-left[ .box-1.small[Before Tuesday] Read Chapters 3 and 4 ] .pull-right[ .box-6.small[Tomorrow: Lab 1] Meet the data. Go to your own lab, and bring a calculator and a laptop ] .box-3.small[Nothing is due this Sunday. The first MindTap work is due January 17 at 6 PM] <style type="text/css"> /* Images sit under the title. These heights leave room for a source line */ .picture img { display: block; margin: 0 auto; max-width: 100%; max-height: 440px; } .picture-small img { display: block; margin: 0 auto; max-width: 100%; max-height: 185px; } .source a { color: inherit; text-decoration: underline; } .anteater img { display: block; margin: 0.15em auto 0; max-height: 105px; } /* This chunk sits at the end because any output before the first slide's "class:" line stops remark from reading that slide's properties */ /* Long titles get two smaller lines inside the 110 px title bar */ .remark-slide-content.long-title h1 { font-size: 1.05em; line-height: 1.05; margin-top: -100px; margin-bottom: 55px; } .source { position: absolute; bottom: 18px; left: 60px; font-size: 0.55em; color: #47505a; } .book-tag { margin-top: 0.7em; font-size: 0.65em; color: #47505a; text-align: right; } table.deck-table { width: 92%; margin: 0.4em auto; border-collapse: collapse; font-size: 0.72em; } table.deck-table.tight td, table.deck-table.tight th { padding: 0.12em 0.6em; } table.deck-table.tighter td, table.deck-table.tighter th { padding: 0.05em 0.6em; } table.deck-table th { border-bottom: 2px solid #244a70; padding: 0.3em 0.6em; } table.deck-table td { border-bottom: 1px solid #c9d1d9; padding: 0.3em 0.6em; } strong.peak { color: #a93e31; } /* The study design, from population to the two groups */ .flow { display: grid; grid-template-columns: 1fr auto 0.8fr auto 1.1fr; align-items: center; gap: 0.5em; margin: 0.9em 0 1em; font-size: 0.72em; } .flow-box { background-color: #f3f3f3; border: 2px solid #cccccc; padding: 0.2em 0.6em; text-align: center; } .flow-box p { margin: 0.25em 0; } .flow-pair { display: grid; gap: 0.5em; } .flow-step { text-align: center; font-size: 0.8em; max-width: 7.5em; } .flow-step p { margin: 0; } .options { display: grid; grid-template-columns: 1fr 1fr; gap: 0.35em 1em; margin-top: 0.6em; margin-bottom: 0.9em; font-size: 0.65em; } .option { background-color: #f3f3f3; border: 2px solid #cccccc; padding: 0.35em 0.6em; } .option.correct { background-color: #b18323; border-color: #b18323; color: white; } .option.wrong { opacity: 0.6; } .poll-respond { display: block; font-size: 0.5em; text-align: center; margin-top: 0.1em; } /* The printed PDF keeps the question and drops the answer slide */ @media print { .remark-slide-container:has(.poll-answer) { display: none !important; } } </style>